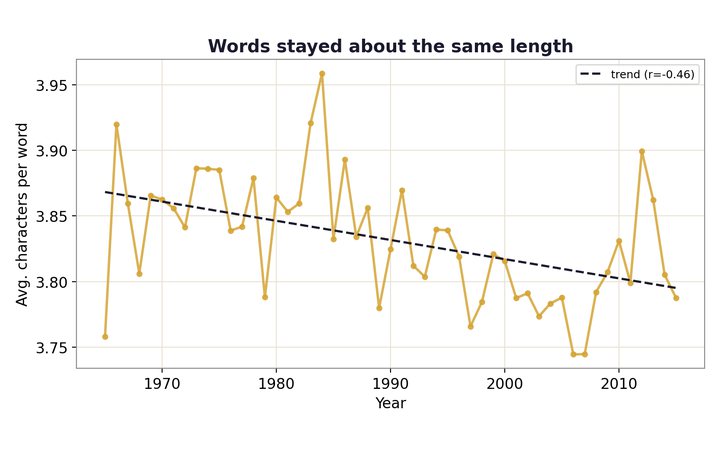
Jeremy Lee

AI engineer · Los Angeles, open to relocation

Jeremy Lee

I build LLM systems and the evals that show whether they work: a frozen test set, a baseline, the cost and latency of every answer, and the failures written down. There are 37 projects here, each with a live site, and 36 with a write-up.

Most recently I led a natural-language analytics platform on Claude and MCP at Kandu, a stroke-recovery health company. Before that: data scientist at InstaAgent (Y Combinator), and nine years as co-founder and Chief Strategy Officer of an education company that grew enrollment 5.2 times. MSBA at UCLA Anderson, December 2026.

Email meResume (PDF)LinkedInGitHub

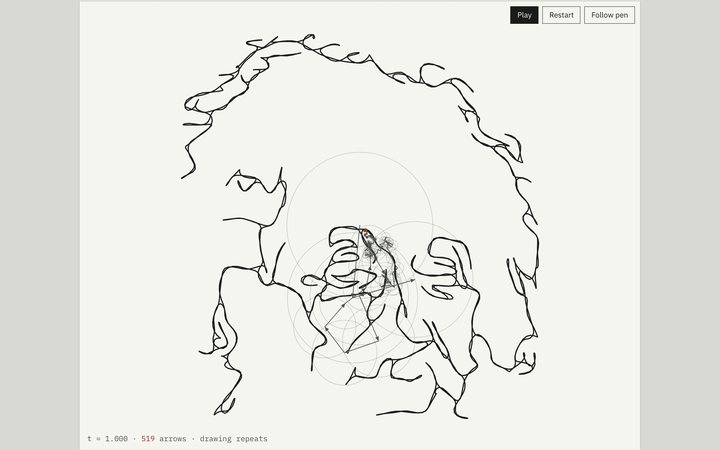
The Berlin Marathon course, 42.6 km as recorded in a public GPX of the 2023 race, redrawn by 160 rotating circles: a Fourier series, the method behind Fourier Pen. I ran it in 2:48.

How I test AI systems

The numbers behind the AI projects

Each row comes from the project's own eval files: a test set frozen before the first run, the baseline it has to beat, what an answer costs at API prices and how long it takes. The last column is the failure I would fix next.

ProjectFrozen eval setResult vs baselineCost per taskLatencyMain failure
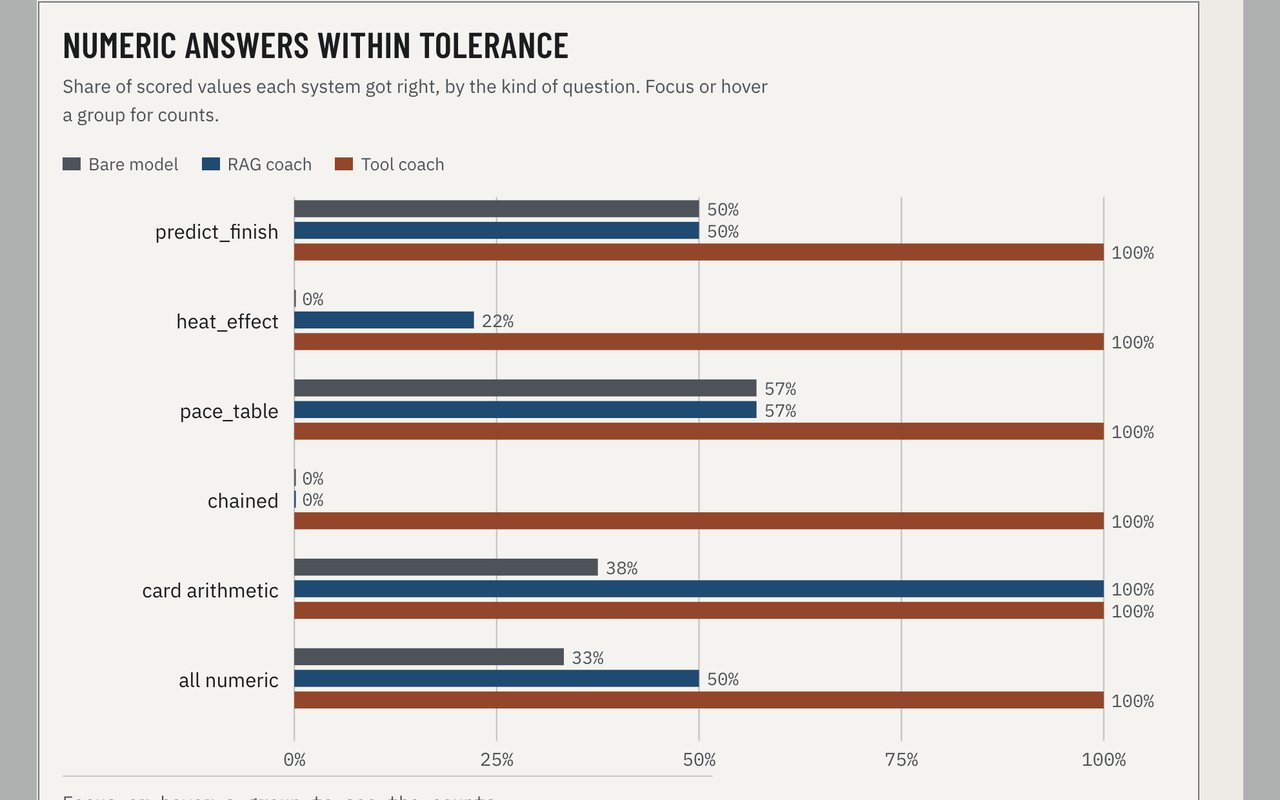
Marathon strategy coach (tools, MCP)43 questions, 42 numeric targets, frozen by hash before any run42 of 42, against 21 for RAG and 14 for the bare model$0.017 median8.4 s median, 14.6 s p95 (n=11)Asks for a missing input instead of answering; 42 of 42 is close to circular, since the targets come from the models it calls
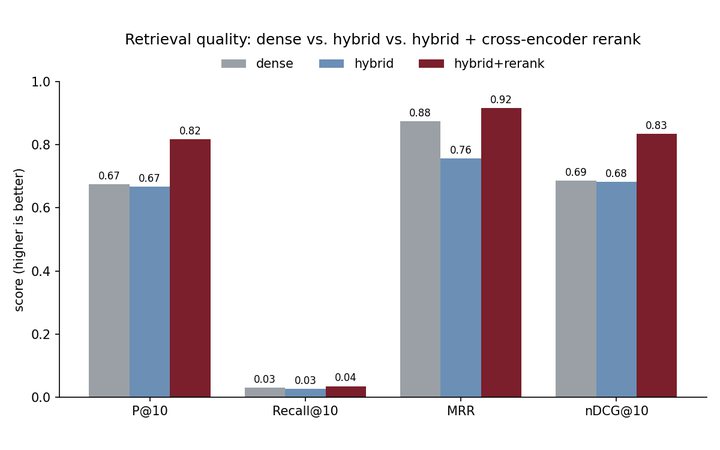
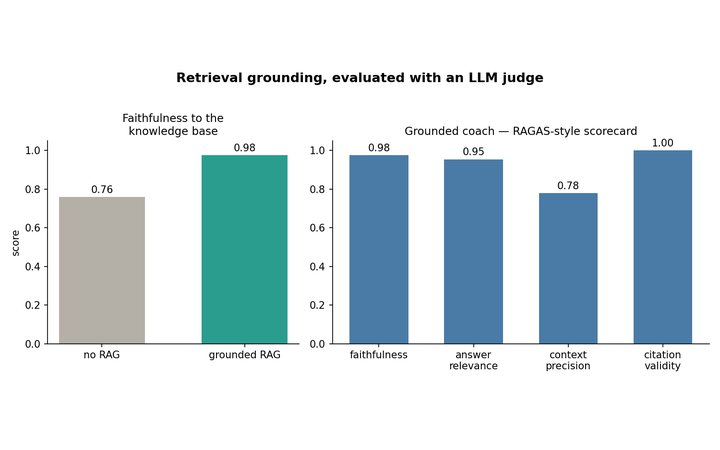
Wine Sommelier RAG12 + 30 rubric queries, the 30 committed before the first runnDCG@10 0.76, against 0.59 for dense retrieval (30 queries)$0 retrieval; $0.13 generationRetrieval 196 ms median, 257 ms p95; answer 8.3 s medianWrong grape or color (20) and an ignored price limit (19) account for half of the 76 missed slots
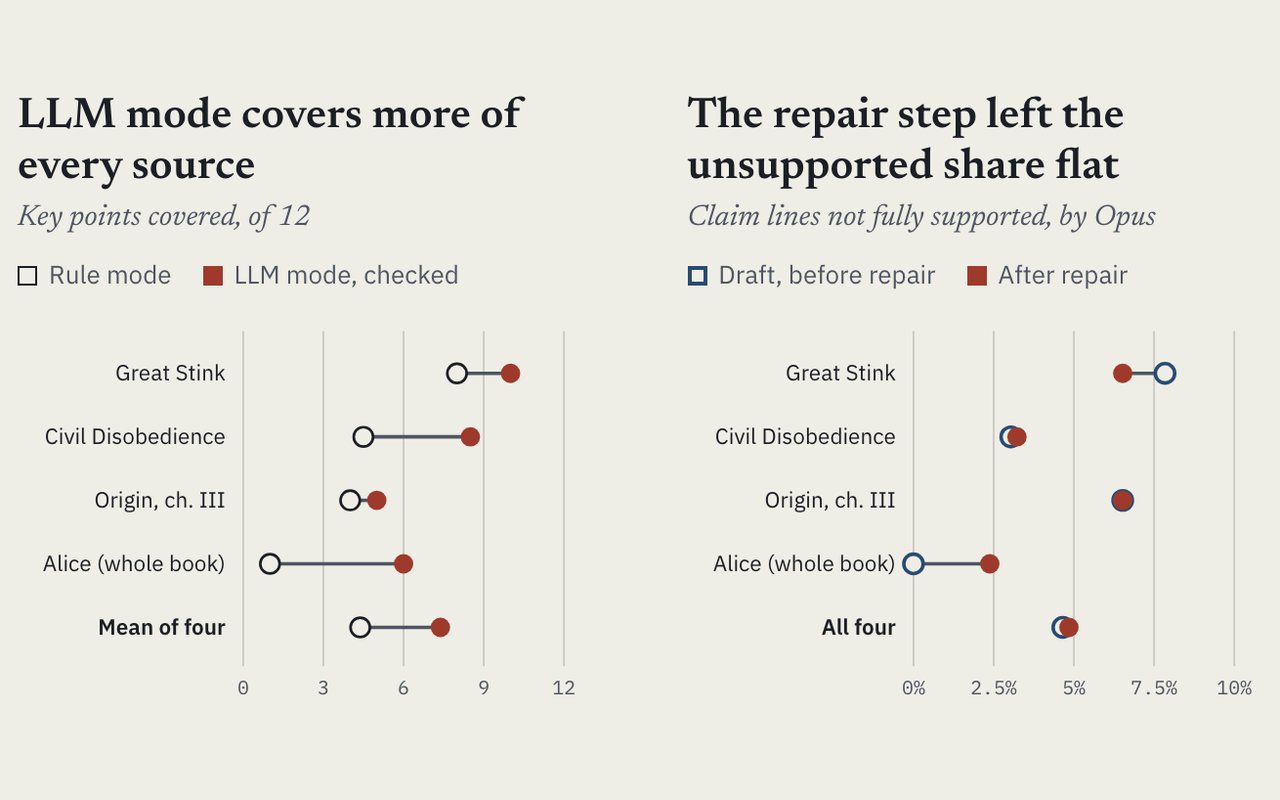
Podcastify4 sources, 12 key points each, committed before generation7.4 of 12 key points, against 4.4 for rule mode; 8 of 172 lines unsupported$0.35 per episode (n=1)3 min 43 s per episode, half of it audioThe repair step did not lower the unsupported rate, and the two checkers disagree
Receipt Auditor (LoRA vs Claude)220 items from 158 merchants the model never sawFine-tuned 1.5B model 90.5%, against 80.0% for Claude zero-shot$0 local; Claude $3.03 per 1,000 itemsLocal 0.19 s median; Claude 3.6 s median, 9.0 s p95Hardware and gasoline items, whose training labels themselves split two ways
Menu Decoder (LoRA vs Claude)303 dishes, held out by dish familyFine-tuned 69.3% allergen recall, against 79.2% for Claude with the full schema$0 local; Claude $56 per 1,000 dishesLocal 6.5 s median; Claude 12.3 s medianRare allergens: sulphites 0 of 11 found. Claude still wins here
SkillCompass question bank645 shipped questions compared with their draftsReview pass rewrote 266; longest-option giveaways down from 37% to 23%; key positions rebalanced to 165/164/158/158$0 (free tiers)Not measuredAs drafted, 64% of keys were option A. Fixed: options shuffle on every showing and the stored bank is rebalanced

Cost is the API-equivalent price reported by the Claude CLI; local-model timings are on an Apple M4 laptop. n is given where it is small.

Experience

Where I have shipped this

  1. Jul to Sep 2026

    Data Engineer, Enterprise Systems and IntelligenceKandu, Los Angeles (stroke-recovery health tech)

    Led the architecture of a natural-language analytics platform on Claude and MCP, from proposal to production: the access model, semantic grounding and promotion gates that let commercial, clinical and operations teams query data themselves. Built the dbt warehouse under it from 13 post-merger systems, under HIPAA and GDPR; identity matching raised record linkage from 75.7% to 97.5%.

  2. Jun to Dec 2026

    Data Analyst, and graduate student researcherUCLA Anderson

    Designed the Office of Inclusive Excellence's first data pipeline (450+ files, versioned and checksum-verified). Research with Prof. Jane Wu on LA's deep-tech cluster (5,022 firms) and with Prof. Yihao Yuan on how LLM voice agents affect debt recovery across 36,000 calls.

  3. Jun 2025 to Mar 2026

    Data ScientistInstaAgent, Los Angeles (AI marketing, Y Combinator)

    Built the LLM content-generation system for nine small-business clients across X, LinkedIn, Instagram and TikTok, which cut content production cost by more than 80%. Deployed engagement and send-time models that lifted engagement 25% and campaign ROI 18%.

  4. 2016 to 2025

    Co-founder and Chief Strategy OfficerCasual Ace Learning Centre, Hong Kong

    Grew from one location to eight with a geo-demographic demand model and A/B pricing tests: enrollment up 5.2 times, revenue 6.7 times, more than 1,000 students. Shipped the company's learning platform end to end, LLM tutor included, and led 28 staff.

Full resume (PDF)

Applied AI

The fine-tuning series

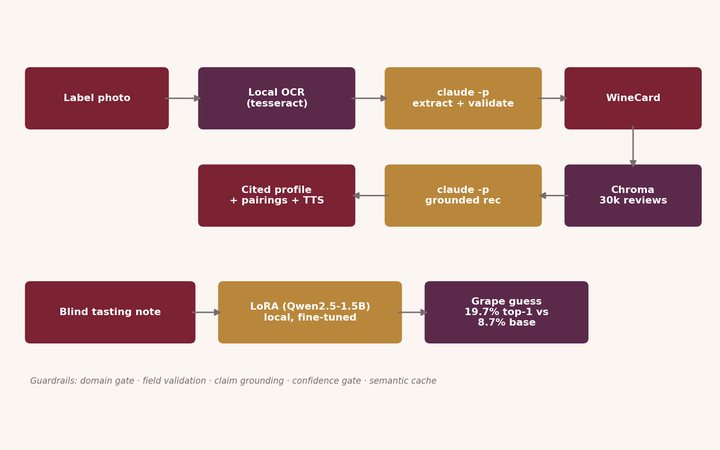
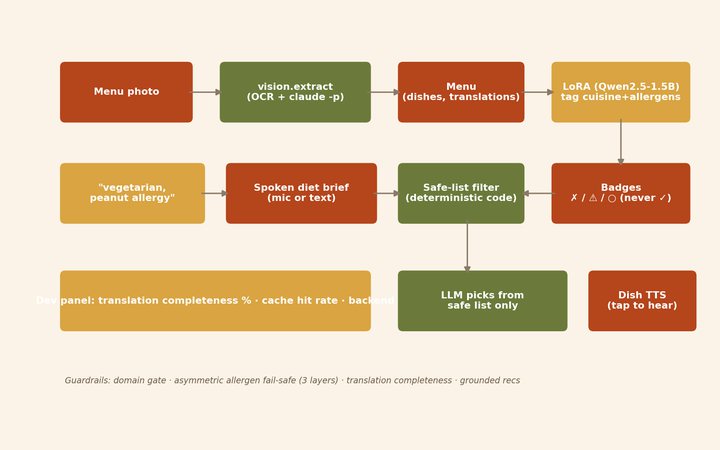
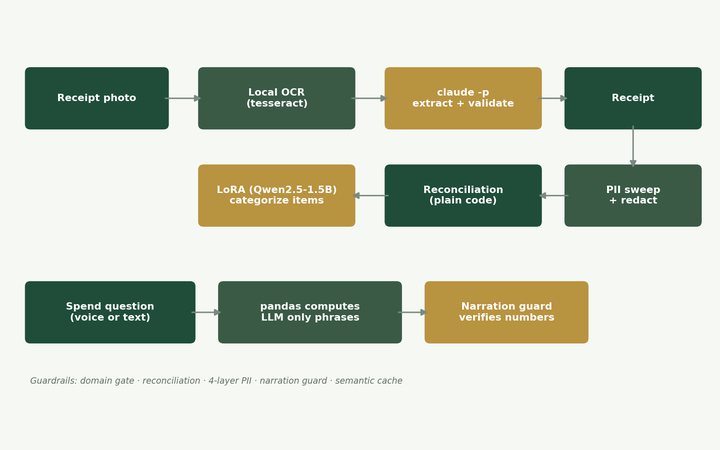
Four photo-to-data apps. Each pairs an LLM pipeline with a small Qwen2.5 model I fine-tuned on my laptop (LoRA) for one step of the task, then benchmarks base, fine-tuned and Claude zero-shot on held-out data.

AppWhat the small model doesFine-tunedClaude zero-shotLinks
Receipt AuditorSpend category for merchants it has never seen90.5%80.0%aSiteWrite-up
Cellar ScannerGrape variety from a blind tasting note (1.5B)27.7%23.0%bSiteWrite-up
Menu DecoderCuisine and 14 allergen tags from a bare dish name99.3% cuisine, 69.3% allergen recall79.2% allergen recallcSiteWrite-up
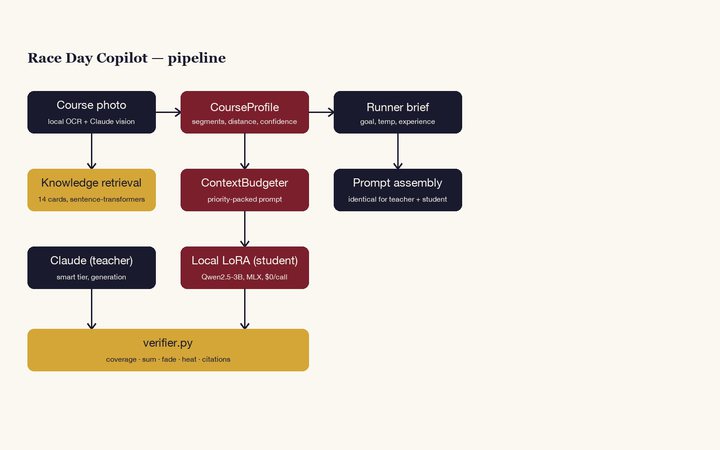
Race Day CopilotKm-by-km pacing plan, checked by six rules (3B)95.7% valid plans; 0.0% pass all six checks90.0% valid; 75.7% passSiteWrite-up
  1. a Clean rerun on 2026-10-28: Claude saw only the merchant text and the 12 labels, with tools off. Most of its misses are noisy labels in the test set (hardware and cables marked other). The first run scored 56.0% with a leaked category list.
  2. b Scored on the same 200 notes, the fine-tuned model is right on 55 and Claude on 46 (sign test p = 0.33), so the gap is within noise.
  3. c Claude needs the full allergen schema in every prompt to get there; the fine-tuned model gets the dish name only.

Analysis

Data stories

Running and wine supply most of the questions.

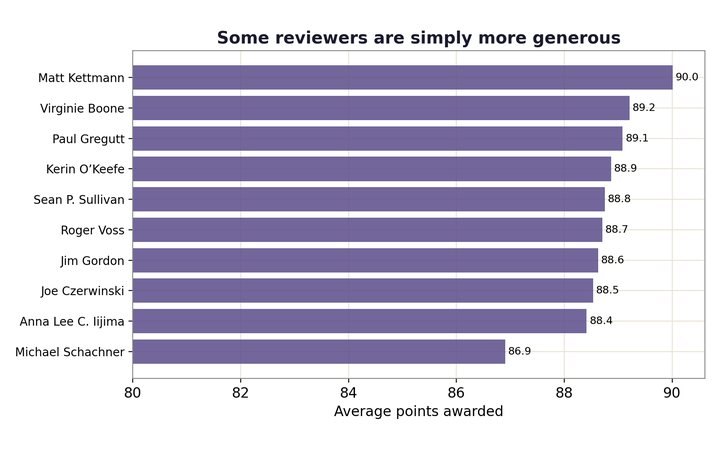
Average points awarded, by reviewer.

Wine Score Inflation cellar

The 100-point wine scale is an 8-point scale

Across about 120,000 unique professional reviews (the source file repeats 9,983) nothing scores below 80, and 85% land between 84 and 92. Some critics are simply more generous than others.

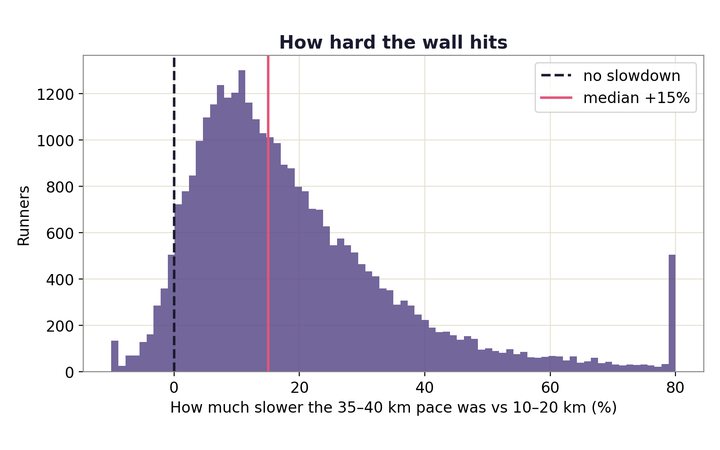
The live split card on the write-up, mid-race.

Hitting the Wall road

Predicting the wall from the first few splits

A model trained on 176,059 Boston finishers from 2014 to 2023 reads your splits as you pass each mat and gives a finish range and the chance of hitting the wall. On the unseen 2024 race it missed by 7.9 minutes at halfway, against 18.1 for even pace.

Average characters per word in hit lyrics, by year.

Are Song Lyrics Getting Simpler? language

Song lyrics got longer, not simpler

Fifty years of Billboard hits doubled in length and grew more repetitive, while the vocabulary stayed about where it was.

Index

All 37 projects

Each project site has its own look, in one of five families. Pick a family to narrow the list.

Products and apps 6

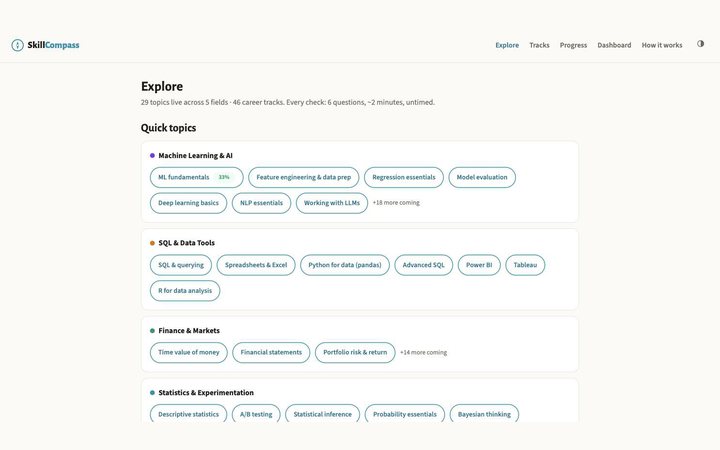
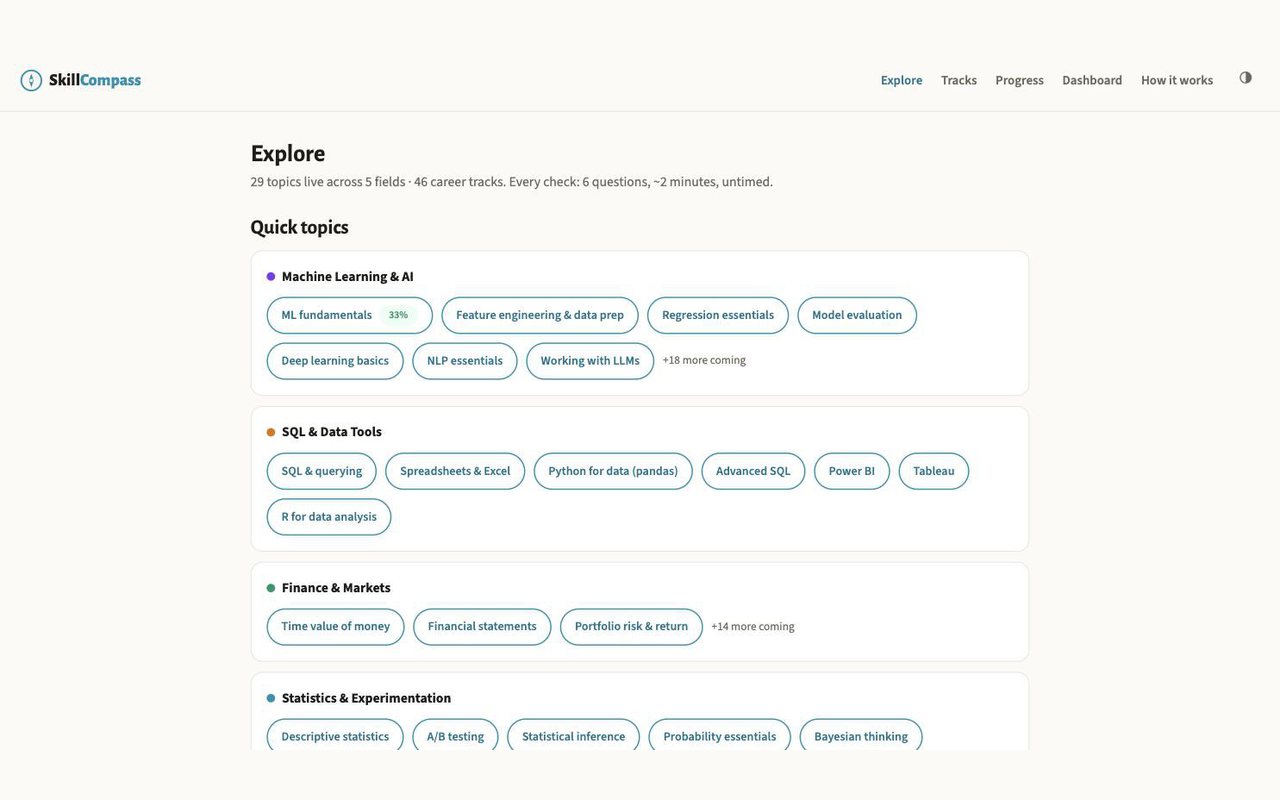
  1. workshopSkillCompassTwo-minute skill checks in 40-plus fields, scored Elo-style, with peer percentiles and three LLM features. Full stack on $0 a month.SiteWrite-upCode
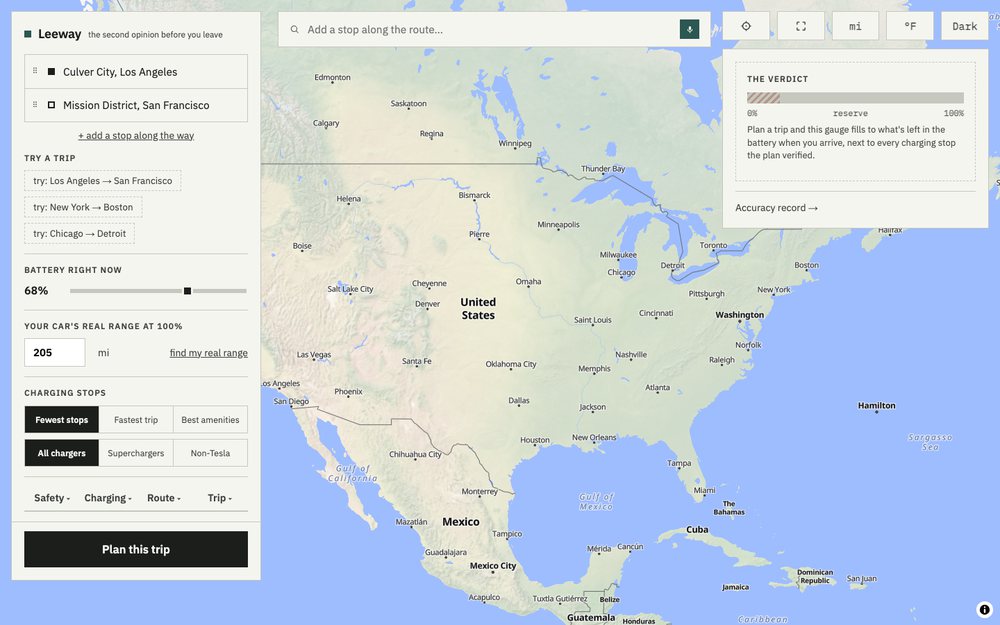
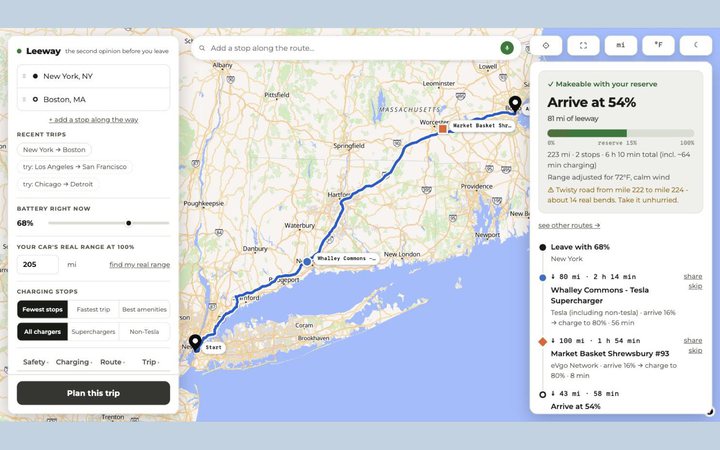
  2. workshopLeewayEV trip planner for a five-year-old battery: range adjusted for elevation and weather, and a detour budget for avoiding risky turns.SiteWrite-upCode
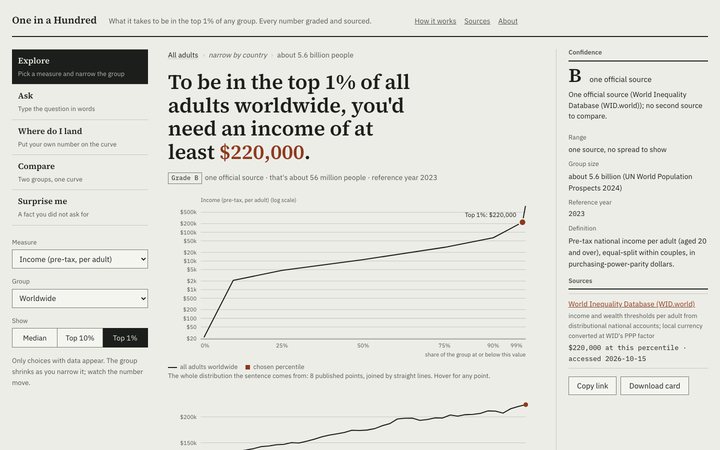
  3. workshopOne in a HundredWhat it takes to be top 1%, top 10% or median: 950 facts from 72 sources, each graded A to D, with the distribution drawn underneath.SiteWrite-upCode
  4. workshopFourier PenAny picture or prompt becomes one continuous line, drawn by a chain of rotating arrows in the browser.SiteWrite-upCode
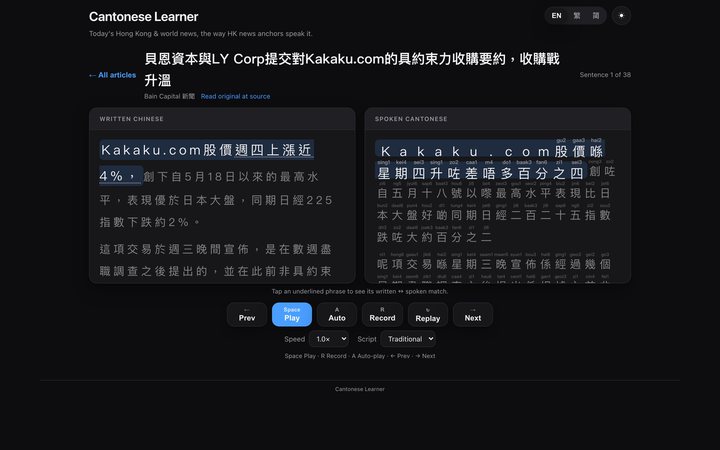
  5. languageCantonese LearnerToday's Hong Kong news rewritten into spoken Cantonese, with neural audio, jyutping and speech grading. Rebuilt daily.SiteWrite-upCode
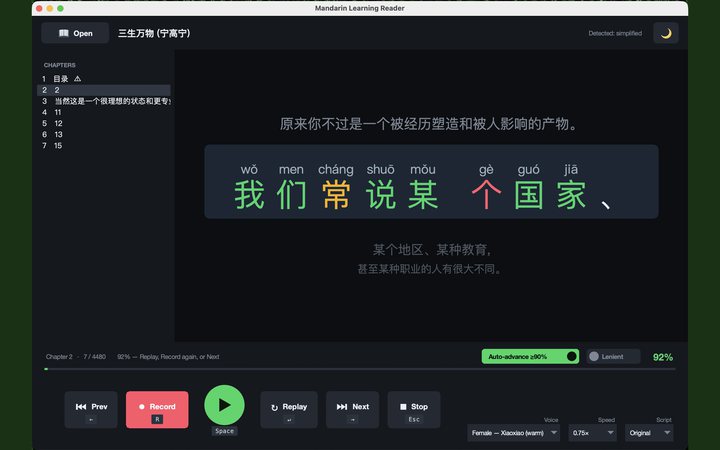
  6. languageMandarin Learning ReaderA tutor built from any Chinese EPUB: pinyin over every character, read-aloud, and offline pronunciation grading.SiteWrite-upCode
The fine-tuning series 4

  1. cellarCellar ScannerWine label photo to a cited profile and pairings; a 1.5B LoRA names the grape from a blind tasting note.SiteWrite-upCode
  2. workshopMenu DecoderMenu photo to translated dishes with cuisine and allergen tags, from a LoRA that needs no schema in the prompt.SiteWrite-upCode
  3. workshopReceipt AuditorReceipt photos to categorized spending; 90.5% category accuracy on merchants the model never saw.SiteWrite-upCode
  4. roadRace Day CopilotCourse map photo to a km-by-km pacing plan that has to pass six deterministic checks.SiteWrite-upCode
Retrieval and agents 4

  1. cellarWine Sommelier RAGPlain-English search over 30,000 wine reviews: BM25 plus dense retrieval and a reranker. On 30 frozen queries nDCG@10 rose from 0.59 to 0.76.SiteWrite-upCode
  2. roadMarathon Strategy RAGA coach that calls my pace and heat models as tools, also served over MCP. On 42 frozen numeric checks it got 42 right, against 21 for plain RAG and 14 for the bare model.SiteWrite-upCode
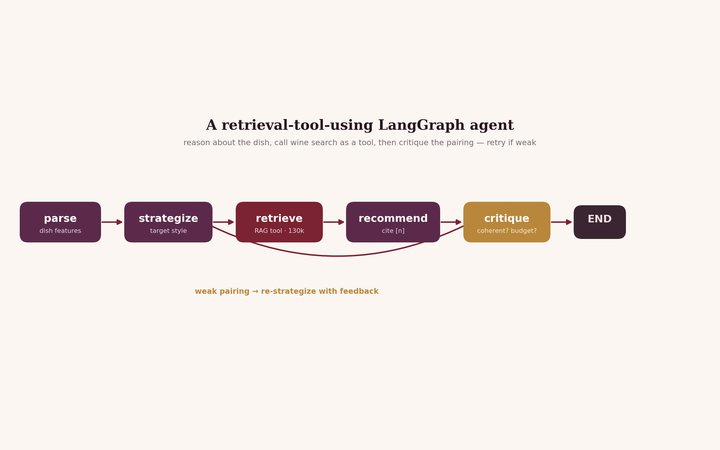
  3. cellarWine Pairing AgentA LangGraph agent that reasons from pairing principles to a style, searches the reviews and critiques its own pick.SiteWrite-upCode
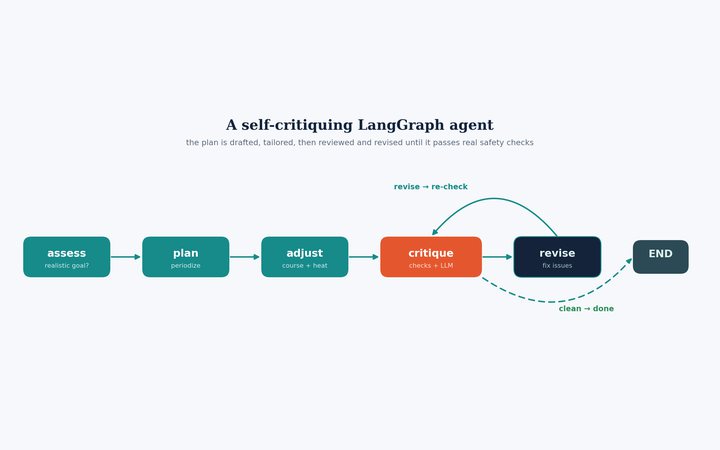
  4. roadMarathon Training AgentA LangGraph agent that drafts a training plan and keeps revising it until it passes explicit safety checks.SiteWrite-upCode
Running and athletics 10

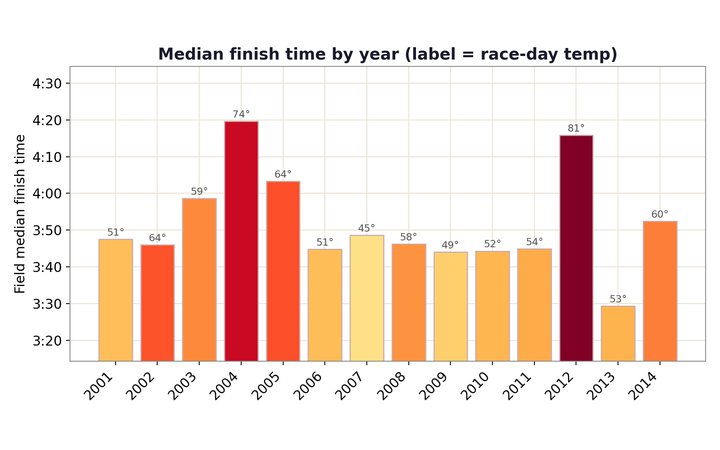
  1. roadThe Heat Tax80 Boston Marathons against ERA5 course weather: heat is free to 55°F, then costs about 0.4% of finish time per degree, with a live race-day forecast.SiteWrite-upCode
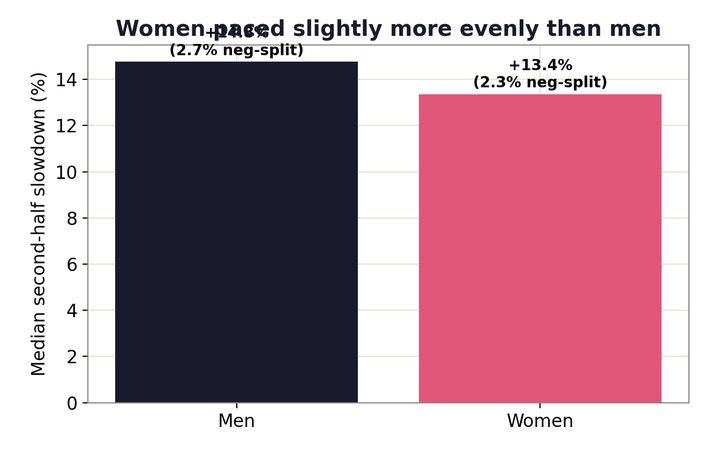
  2. roadThe Negative-Split MythOnly 2.5% of 31,912 Boston 2014 finishers ran a negative split; across eight Boston years the share runs from 2.4% to 10.8%.SiteWrite-upCode
  3. roadHitting the WallEight Boston years of 5 km splits and a live race predictor: enter splits as you pass each mat for a finish range and wall risk, tested on 2024.SiteWrite-upCode
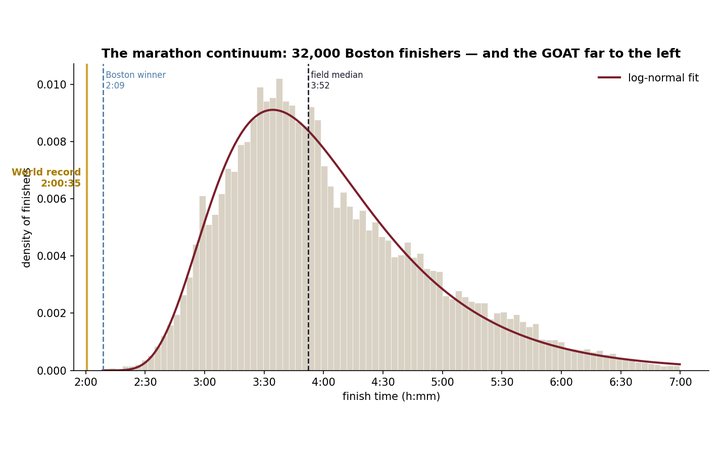
  4. roadPerformance ContinuumWhere any marathon time sits among 31,842 finishers, and how far out the world record is, using extreme-value theory.SiteWrite-upCode
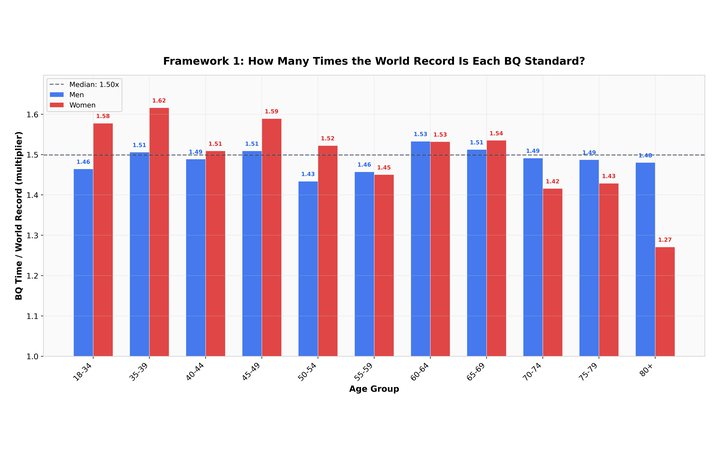
  5. roadBoston BQ FairnessAre Boston qualifying times equally hard for every age and gender group?SiteWrite-upCode
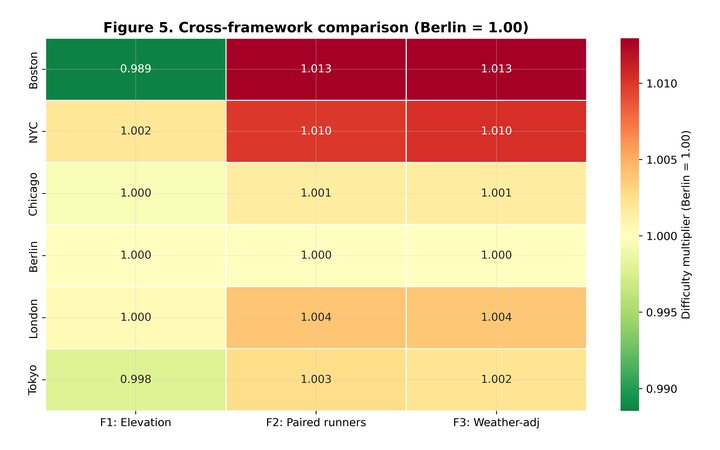
  6. roadMajors Course DifficultyThree ways to rank the six Majors by difficulty, tested on simulated races with planted penalties.SiteWrite-upCode
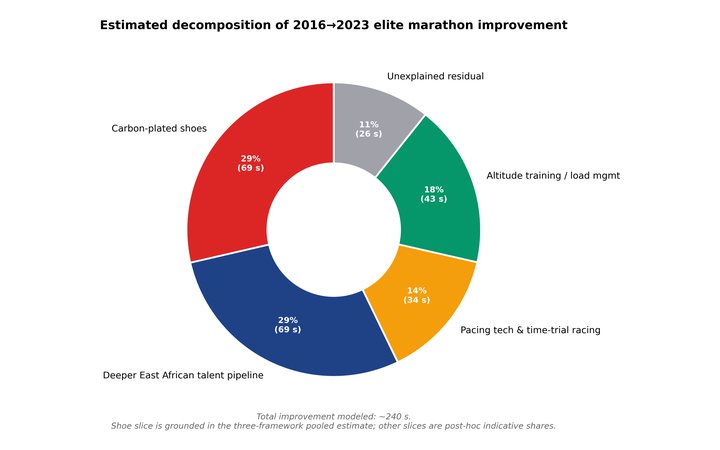
  7. roadMarathon Shoe RevolutionHow much of the recent drop in marathon times comes from the shoes.SiteWrite-upCode
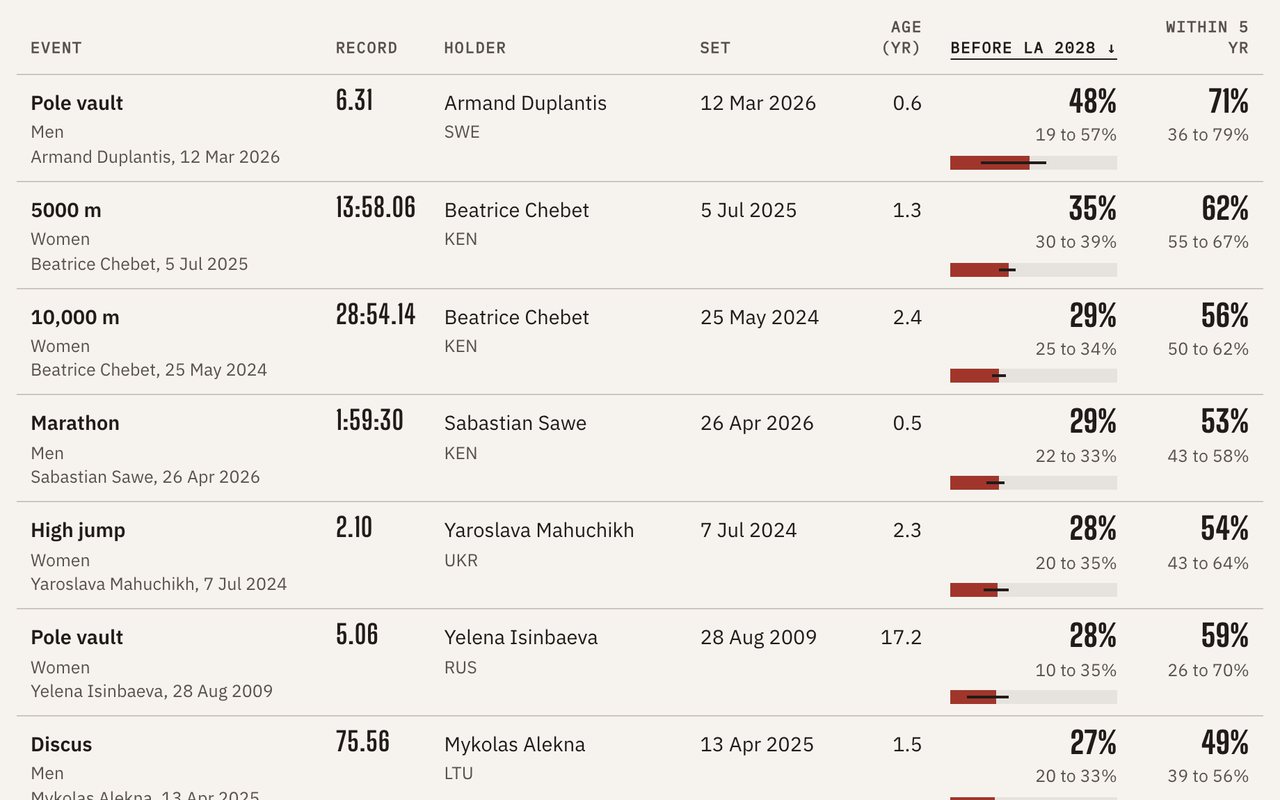
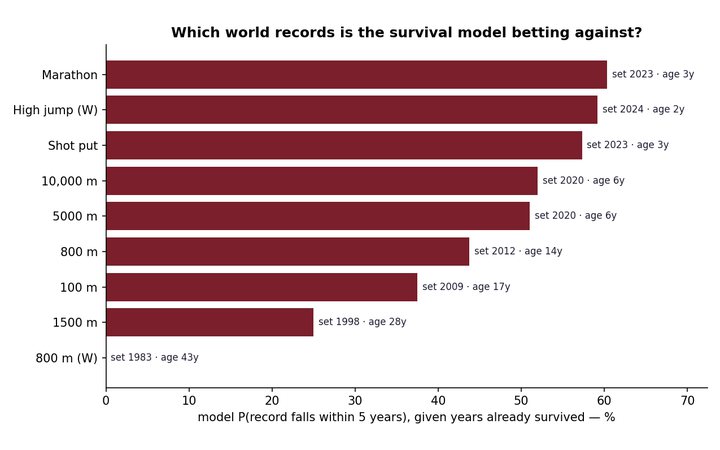
  8. trackWorld-Record Half-LivesEvery Olympic event's world-record progression, a frailty survival model tested on 2011 to 2025, and the odds each current record falls before LA 2028.SiteWrite-upCode
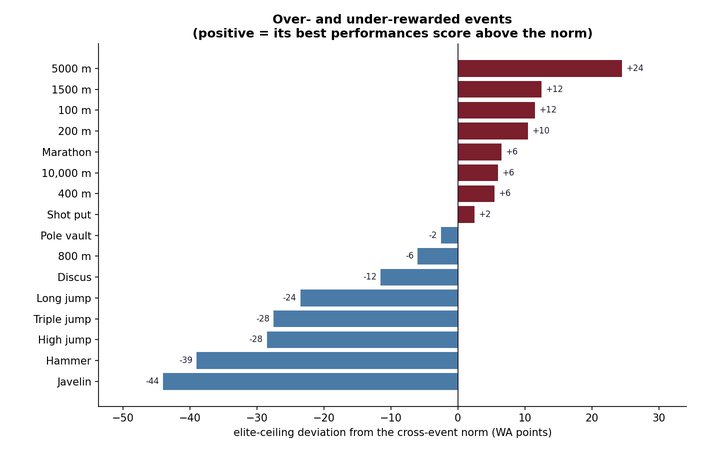
  9. trackScoring-Table FairnessKruskal-Wallis tests on 6,400 elite marks: the best in some events score 68 points more than in others.SiteWrite-upCode
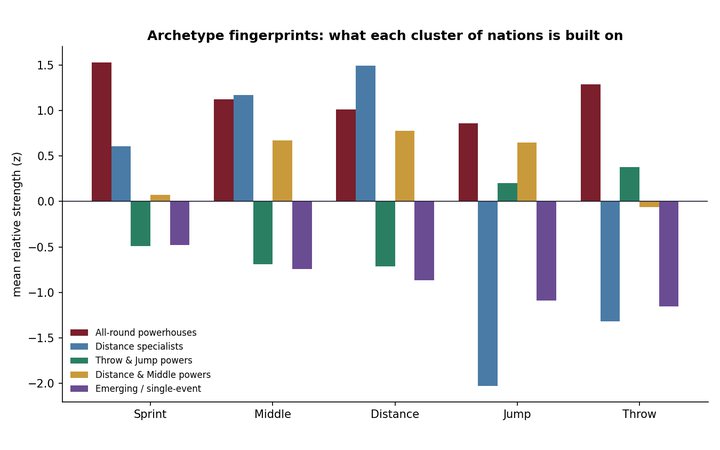
  10. trackNational Strength ProfilesK-means and PCA on 43 nations across five disciplines, which fall into five profiles.SiteWrite-upCode

Wine, words and money 8

  1. cellarWine Score InflationNothing in about 120,000 unique reviews scores below 80, and 85% land between 84 and 92.SiteWrite-upCode
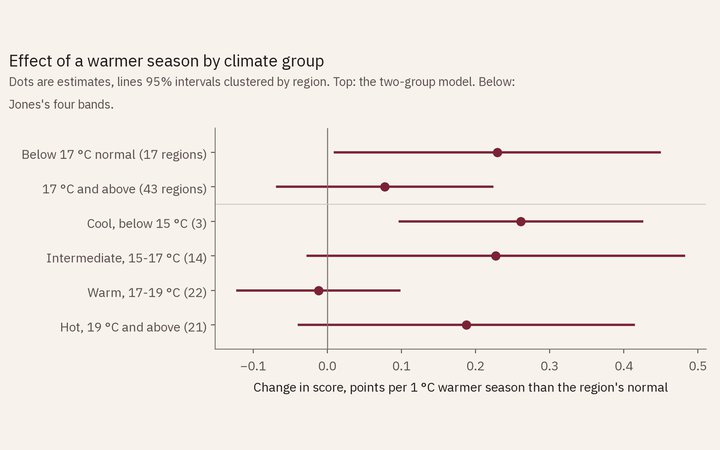
  2. cellarVintage HeatA season 1 °C warmer than normal moved scores by 0.24 points in cool regions, across 55,597 reviews and 55 regions. The checks weaken even that.SiteWrite-upCode
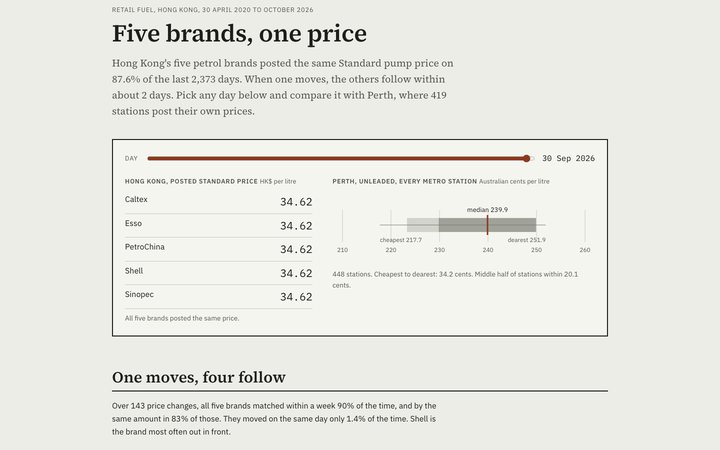
  3. workshopFuel LockstepHong Kong's five petrol brands post one price on 88% of days. Six years of posted prices screened against import costs, with Perth and Los Angeles for contrast.SiteWrite-upCode
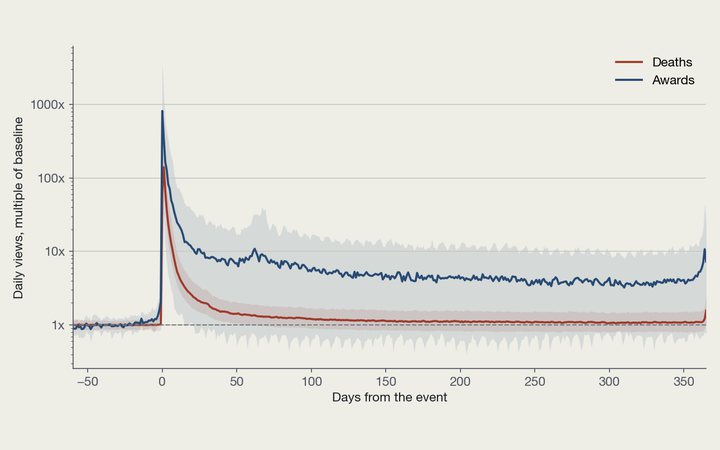
  4. languageFame Half-LifeHalf the extra Wikipedia attention a death brings is gone about two days after the peak; a year later the page still draws 1.08 times its old traffic. 1,905 deaths and 178 awards, 2016 to 2025.SiteWrite-upCode
  5. languageAre Song Lyrics Getting Simpler?Fifty years of Billboard hits got longer and more repetitive, but the vocabulary held.SiteWrite-upCode
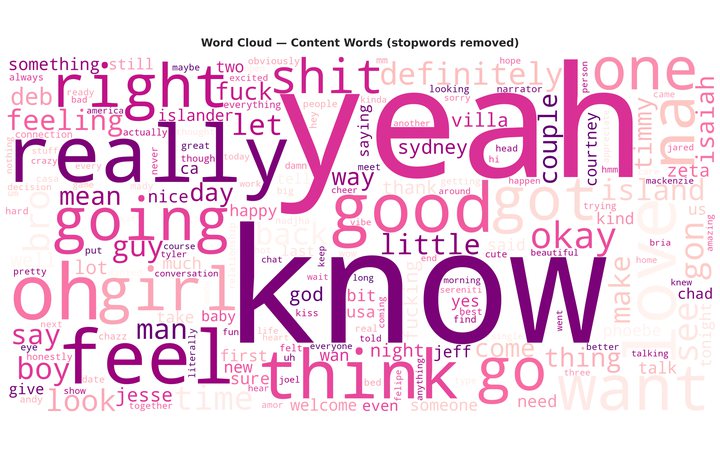
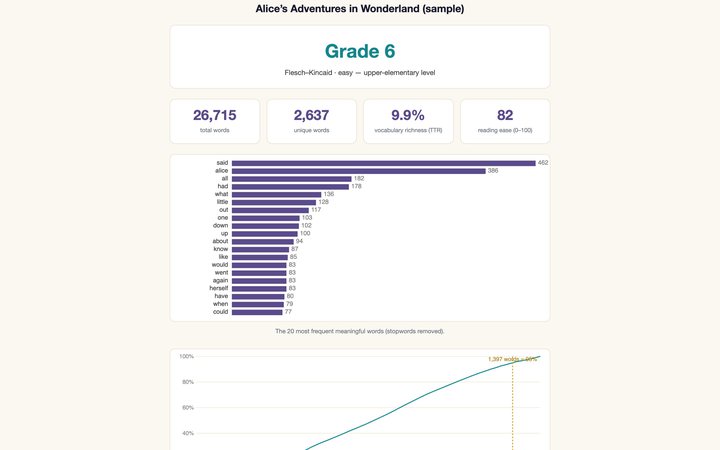
  6. languageLove Island Lexical AnalysisThe top 100 words make up 61% of everything said; about 1,250 words cover 95%.SiteWrite-upCode
  7. languageEPUB Reading-Level AnalyzerGrade level, vocabulary richness and a word-coverage curve for any EPUB, computed in the browser.SiteWrite-upCode
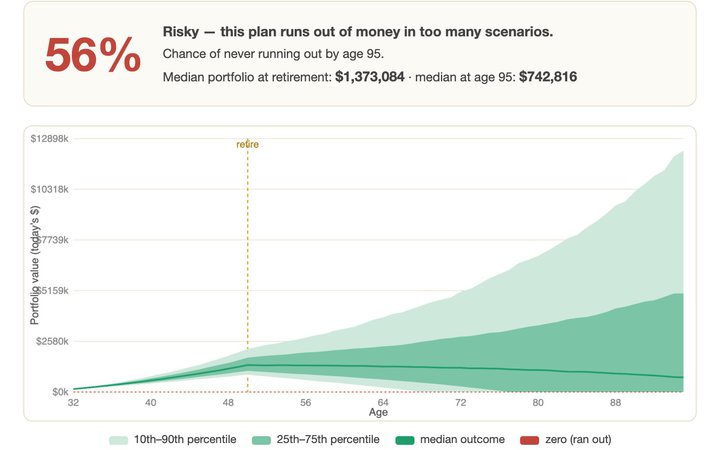
  8. workshopWhen Can I Retire?Replays your retirement plan through every start year of US market history since 1871, and finds the smallest change that reaches 90%.SiteWrite-upCode

Small tools 5

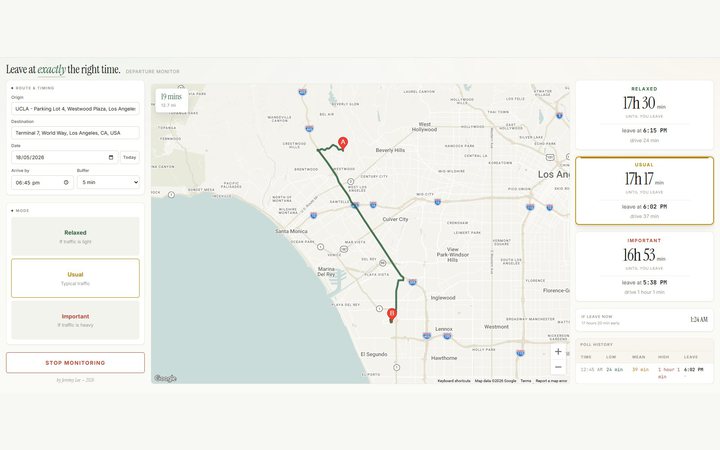
  1. workshopLeave Time OptimizerWhen to leave to arrive on time, from Google Maps traffic estimates.SiteWrite-upCode
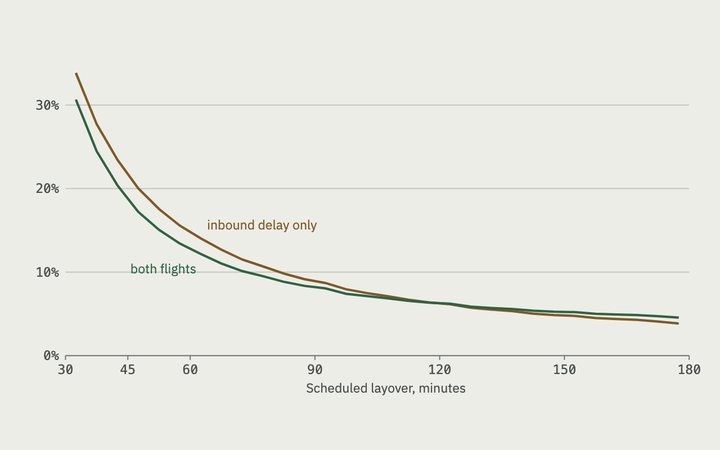
  2. workshopConnection OddsA 45-minute layover at a US hub missed 17% of the time, from 23 million flights. The lookup gives the layover you need for 95%.SiteWrite-upCode
  3. languageEPUB to AudiobookA desktop app for read-along audiobooks in English, Mandarin and Cantonese.SiteWrite-upCode
  4. languagePodcastifyTurns a whole book or article into a two-host episode where every claim cites the sentences it came from and is checked before it is voiced.SiteWrite-upCode
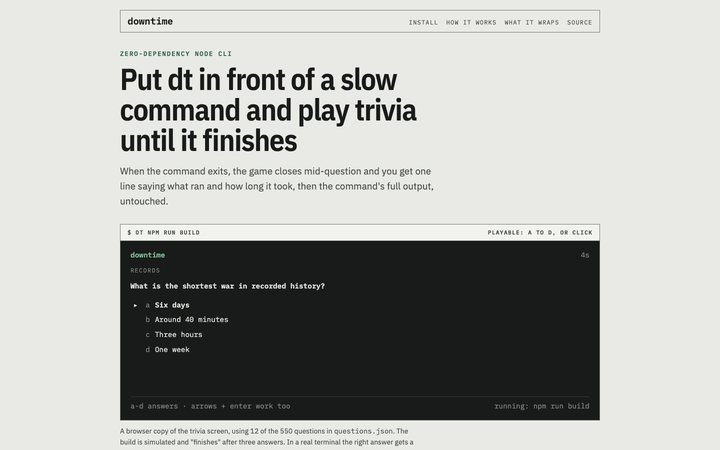
  5. workshopdowntimeA zero-dependency CLI that fills a long build with terminal trivia, then hands back the output untouched.SiteCode

About

Background

I spent nine years running a business before I wrote production code. I co-founded Casual Ace Learning Centre in Hong Kong and, as Chief Strategy Officer, grew enrollment 5.2 times to more than 1,000 students across eight locations, and shipped its learning platform, LLM tutor included. That is why my projects report cost and failure modes next to accuracy. I came to AI engineering through an MSBA at UCLA Anderson (GPA 3.92), after graduate analytics coursework at Georgia Tech and a BBA in Accounting and Finance from the University of Hong Kong.

Outside work I have run 14 marathons, with a best of 2:48 in Berlin, and I hold WSET Level 3 in wine. Between them they account for most of the questions on this page.

lyhjeremy@gmail.comResume (PDF)LinkedIn

Modeling
scikit-learn, PyTorch, XGBoost. Regression, classification, clustering, time series, survival analysis, causal inference, A/B testing.
LLM systems
Claude and MCP, tool use, agents (LangGraph), RAG (BM25, dense, cross-encoder reranking), LoRA fine-tuning, evals with frozen gold sets and LLM judges, grounding checks, cost and latency measurement.
Engineering
Python, TypeScript, SQL, FastAPI, React, Git, CI/CD, GCP, Claude Code.
Optimization
Gurobi; LP, IP, QP and non-convex programs; branch-and-bound, duality, Monte Carlo simulation.
Data
Snowflake, dbt, Airflow, Spark, R, Tableau, Power BI. Apps deployed on Render, Vercel and GitHub Pages.